Executive Summary:
- Rule-based systems catch only known patterns; AI fraud detection learns normal behavior and flags deviations in real time.
- Supervised models catch known fraud, anomaly detection catches new schemes, and deep learning and graph neural networks expose multi-step sequences and fraud rings.
- Behavioral biometrics and device intelligence stop account takeover without adding friction for genuine users.
- Explainability techniques such as SHAP and LIME turn model decisions into reasons that analysts, customers, and regulators can act on.
- Fraud models need continuous retraining, bias testing, and privacy-by-design governance to stay effective and compliant.
Present-day companies lose a significant portion of their yearly revenue to fraud. This is, in part, due to the traditional rule-based systems that can’t keep up with modern fraud schemes. Fraudsters now use automation, synthetic identities, and deepfakes to test defenses at machine speed, while static rules only catch the patterns someone has already written down.
The impact shows up on both sides of the ledger. Missed fraud drains revenue directly. Over-cautious rules block genuine customers, swell manual review queues, and erode trust.
That is why AI-powered fraud detection systems have become the standard rather than the exception. Machine learning fraud detection models learn what normal behavior looks like, score every event in milliseconds, and adapt as new fraud patterns emerge. They track transactions around the clock and spot suspicious activity immediately.
This guide explains how AI and machine learning combat AI financial fraud threats, from the business case to the algorithms behind it, including supervised learning, anomaly detection, deep learning, graph neural networks, and NLP. It also covers explainability, continuous learning, implementation, and the challenges leaders must plan for.
Why Are Traditional Systems Failing Against the Growing Scale of Financial Fraud?
Traditional rule-based systems fail because they only detect fraud patterns that analysts have already defined. Fraudsters change tactics faster than rules can be written, tested, and deployed, so static thresholds miss new schemes while flagging genuine customers. AI fraud detection replaces fixed rules with models that learn from data and adapt continuously.
Financial fraud now operates at an industrial scale. Global payment card fraud losses reached $33.41 billion in 2024, and the Nilson Report1 projects they will rise to $41.06 billion by 2030. In the US, consumers reported $15.9 billion in fraud losses to the Federal Trade Comission2 in 2025, and the FBI’s Internet Crime Complaint Center3 recorded $20.9 billion in cybercrime losses. Inside organizations, the ACFE’s Occupational Fraud report4 estimates that companies lose 5% of revenue to fraud each year.
The nature of fraud has changed, too. Synthetic identity fraud stands out as perhaps the most concerning trend. Deepfake technology presents another major concern for security professionals.
Today, the dark web offers fraud-as-a-service packages that put advanced attack capabilities into the hands of nearly anyone willing to pay. Cross-channel fraud is more common. A single attack may start with a phishing email, move to a spoofed support call, and end in a mobile app.
This is why AI vs rule-based fraud detection is a business decision. Rule-based systems fall short on three fronts:
- Speed: Traditional approaches use fixed rules that fraudsters can study and bypass. By the time a new rule is live, the attack pattern has already shifted.
- Coverage: These systems work well with known patterns (e.g., someone making purchases across multiple continents daily). However, they fall flat when confronting unknown patterns or clever variations of existing patterns.
- Customer Friction: Broad thresholds flag large volumes of legitimate transactions. Every false decline frustrates a genuine customer and adds to the review backlog. This is a problem that is especially visible in credit card fraud detection.
To combat these threats, organizations must transform their approach from reactive to proactive security postures. This shift sits at the heart of AI in financial services and how fraud prevention fits the broader AI transformation.
“Fraud today moves at a speed of an API call. Rules-based fraud engines, however well-designed, are perpetually one step behind the fraudsters, who adapt more frequently.”
– Sanjay Malhotra, Governor, Reserve Bank of India (RBI)
What Types of Financial Fraud Can AI Detect?
AI can detect credit card fraud, insurance fraud, identity theft, synthetic identity fraud, account takeover, and mortgage or loan fraud. Each type leaves a different data signature. and machine learning models are trained to recognize those signatures at scale.
The table below maps six common fraud types to the signals AI uses to catch them:
| Fraud Type | What It Looks Like | How AI Detects It |
|---|---|---|
| Credit card fraud | Stolen card details used for card-not-present purchases, card testing, or cloned-card transactions | Credit card fraud detection AI scores each transaction in real time on amount, merchant, location, device, and velocity, using models trained on confirmed chargebacks |
| Insurance fraud | Staged, inflated, or duplicate claims; padded medical bills | Insurance fraud detection AI scores claims, applies NLP to adjuster notes and documents, and links claimants, providers, and repair shops |
| Identity theft | Real customer data used to open or access accounts | Document and liveness checks, identity data verification, and behavioral mismatch detection |
| Synthetic identity fraud | Real and fabricated data combined into a new "person" who builds credit before busting out | Synthetic identity fraud detection uses graph analysis of shared phones, addresses, and devices across applications |
| Account takeover | A fraudster gains login access through phishing, credential stuffing, or SIM swap | Account takeover prevention AI combines behavioral biometrics, device fingerprinting, and login anomaly detection to trigger step-up authentication |
| Mortgage/loan fraud | Falsified income, employment, or property data in applications | Document AI cross-checks pay stubs, bank statements, and tax records; anomaly detection flags unusual application patterns. |
Synthetic identities deserve special attention. These fabricated identities prove especially difficult to spot because they often include legitimate data elements. They pass checks that evaluate one application at a time, so catching them requires looking at relationships across applications, which is where graph-based machine learning comes in.
How Does AI Detect Fraud?
AI detects fraud by ingesting transaction, device, and behavioral data, learning what normal activity looks like, and scoring each new event for risk in milliseconds. High-risk events are blocked or escalated, and every confirmed outcome is fed back to retrain the models. Machine learning algorithms are the engine behind each step.
“Once you train a model, the speed you can catch things is in milliseconds. It’s incredible.”
– Amiram Shachar, Co-Founder & CEO, Upwind
At the business level, AI fraud detection does one thing: it decides, in real time, whether an event is safe to approve. Behind that decision sits a four-part system:
- Data Ingestion: These systems need to handle both structured data (transaction records, account information, demographic details) and unstructured data (emails, chat logs, social media interactions).
- Pattern Recognition: Machine learning models identify the signals that separate legitimate activity from fraud.
- Real-Time Decision Engine: Smart decision engines evaluate transactions in milliseconds. They use risk-scoring systems that consider hundreds of variables simultaneously and determine the probability of fraud.
- Feedback and Training: Confirmed fraud and false positives flow back into the models, so accuracy improves over time.
Real-time fraud detection AI is only as strong as the models inside it. Hybrid systems that combine one or more of these models work better than single-model approaches. The sections below break down the fraud detection algorithms that do the heavy lifting.
Supervised Learning: Training on Known Fraud Patterns
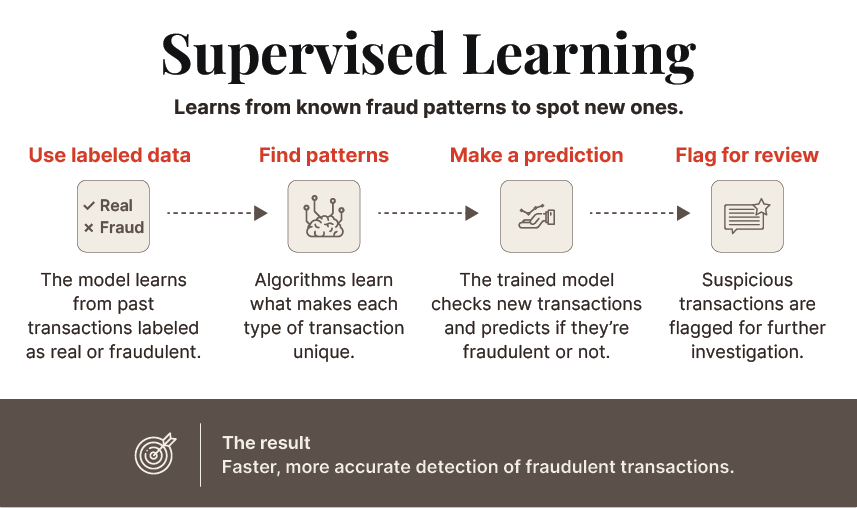
Supervised learning fraud detection treats fraud as a machine learning classification problem. In this method, algorithms are trained using data that is already labeled as either real or fraudulent transactions. The model learns to recognize patterns for each type. Common algorithms include logistic regression for transparent baseline scoring, random forests that combine many decision trees, and gradient boosting, which performs strongly on tabular transaction data.
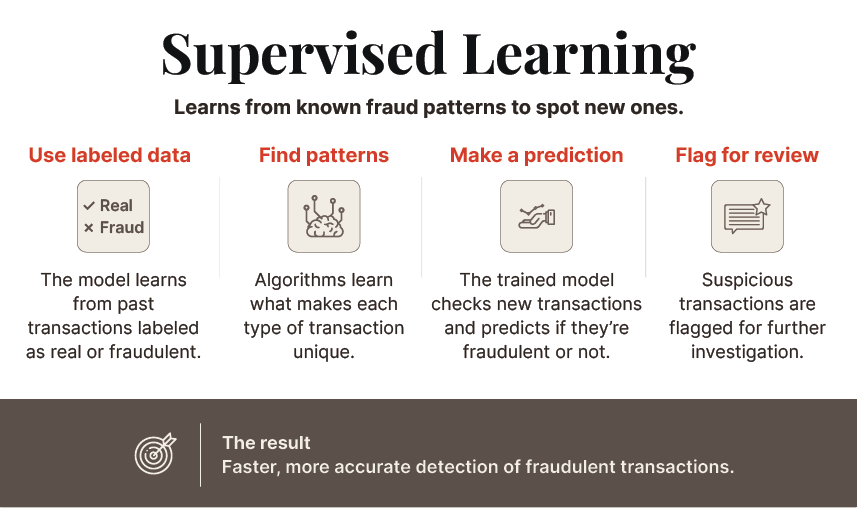
The challenge is labeled data. Confirmed fraud makes up a tiny fraction of transactions, and labels often arrive weeks later through chargebacks or investigations. This class imbalance pushes naive models to predict “legitimate” every time.
Teams counter it with SMOTE (Synthetic Minority Oversampling Technique), which generates synthetic fraud examples for training, and with cost-sensitive learning that penalizes missed fraud more heavily. For example, a bank might use supervised ML to look at past transaction data to predict if a new transaction is likely to be fraud based on patterns they have already identified.
Anomaly Detection: Catching Unknown Fraud Patterns
Unsupervised ML fraud detection looks at unlabeled data to find hidden patterns or groups. This method is helpful for identifying new types of fraud. Anomaly detection fraud AI learns a baseline of normal behavior and flags anything that deviates from it; no prior fraud examples needed. Three techniques dominate:
- Isolation forest: Randomly splits the data; fraudulent events are typically isolated in fewer splits than normal ones, which makes isolation forest fraud scoring fast at scale.
- Autoencoders: Neural networks that learn to reconstruct normal transactions. A high reconstruction error signals an anomaly.
- One-class SVM: Draws a boundary around normal behavior and flags points that fall outside it.
For example, an online store might use unsupervised ML to discover unusual buying behaviors from an account that could signal fraud, such as a sudden spike in transactions. Flagged anomalies are reviewed, labeled, and fed back into supervised models.
Neural Networks & Deep Learning for Complex Pattern Recognition
Some fraud only becomes visible across a sequence of events: a password reset, a new payee, a small test transfer, then a large withdrawal. Deep learning fraud detection models are built to read these sequences across multiple transactions over time.
- LSTM (Long Short-Term Memory) networks: LSTM fraud detection models remember earlier steps in a customer’s history when scoring the latest transaction.
- Transformer-Based Models: Use attention to weigh which past events matter most, capturing long, multi-step fraud sequences across sessions and channels.
- CNNs (Convolutional Neural Networks): Detect local patterns in structured representations of activity, such as time-windowed transaction grids.
Neural network fraud models need more data and compute than tree-based models, but they excel at the complex, multi-dimensional patterns that coordinated fraud leaves behind.
Graph Neural Networks: Exposing Synthetic Identity Rings
Most models score one transaction or applicant at a time. Fraud rings exploit that blind spot. Graph neural network fraud detection analyzes the connections instead.
In a financial graph, nodes represent entities, such as accounts, customers, devices, IP addresses, phone numbers, and merchants. Edges represent the relationships between them, such as a shared device, a common address, or a money transfer. A graph neural network (GNN) learns from both the attributes of each node and the structure of its neighborhood.
This is what makes GNN-based synthetic identity fraud detection so effective. A single synthetic applicant may look clean. But when dozens of “unrelated” applicants share a handful of devices, phone numbers, and IP ranges, the graph exposes the ring.
The same approach powers other network fraud detection ML use cases, including money mule networks, collusive merchants, and coordinated insurance claims. Because the model learns patterns of connection rather than fixed rules, it can flag a ring as it forms, often before the “bust-out,” when synthetic identities max out their credit lines and disappear.
NLP for Detecting Fraud in Documents, Communications & Logs
Much fraud evidence is written, not numerical. NLP fraud detection applies language models to insurance claims, loan documents, chat transcripts, emails, and system logs.
- Entity Extraction: Pulls names, dates, amounts, and addresses from documents so they can be cross-checked against other records.
- Inconsistency Detection: Flags contradictions, such as an accident description that doesn’t match the reported damage, or declared income that differs from bank statements.
- Tone and Intent Classification: Identifies urgency, pressure, or scripted language typical of social engineering and business email compromise.
AI document fraud detection turns unstructured text into risk signals that feed the same decision engine as transaction data, making text analysis a core layer of fraud prevention.
Understanding the Role of Machine Learning in Shaping Businesses
How Do Behavioral Biometrics and Device Intelligence Prevent Fraud?
Behavioral biometrics prevent fraud by verifying users through how they interact while device intelligence checks the device and network behind each session. Together, they detect account takeover passively and add friction only when risk is high.
Behavioral analysis adds another layer of protection. The technology builds detailed user profiles by collecting data from various interaction points. These include typing patterns, mouse movements, screen pressure on mobile devices, and browsing habits. These profiles act like digital fingerprints that help organizations spot potential fraudsters quickly.
Device intelligence fraud detection adds context: device fingerprinting, operating system and browser configuration, emulator or remote-access tool detection, IP reputation, and location consistency.
The real value is passive authentication AI. Genuine users log in and transact without extra steps. When signals don’t match, the system triggers step-up authentication, such as a one-time passcode or biometric check, instead of a hard decline.
This matters more as criminals use generative AI to create increasingly convincing fakes. With deepfakes, fraudsters can now bypass biometric security measures that once seemed impenetrable. Behavioral and device signals are far harder to fake than a face or a voice, so behavioral biometrics fraud prevention stops attackers even when they hold valid credentials.
How Is AI Fraud Detection Used Across Banking, Insurance & Ecommerce?
Banks use AI fraud detection for transaction monitoring and wire transfer fraud, insurers use it for claims integrity scoring and medical billing fraud, and e-commerce companies use it to stop card-not-present fraud, return fraud, and bot-driven credential stuffing. The models differ, but the goal is the same: stop fraud without slowing genuine customers.
Banking: AI banking fraud prevention sits inside the payments flow, so a decision must land before a wire transfer clears. Explore AI in banking operations, including real-time fraud monitoring and compliance.
Insurance: AI insurance fraud detection works best at first notice of loss, when suspicious claims can be routed to special investigation units before payout without delaying honest policyholders.
Ecommerce: Ecommerce fraud prevention AI must balance protection with conversion, because every false decline at checkout is a lost sale.
The same principles extend beyond these sectors. From AI in fintech, where fraud prevention underpins financial technology trust, to AI in accounting and how fraud detection integrates with financial management, and AI for supply chain integrity and logistics fraud prevention.
How Does Model Explainability Reveal Why the AI Flagged a Transaction?
Explainable AI reveals why a transaction was flagged by ranking the factors that drove its risk score. For example, an unfamiliar device, a new payee, and an unusually high amount. Techniques such as SHAP and LIME convert complex model outputs into reason codes that analysts, customers, and regulators can understand.
All too often, modern AI models function as “black boxes”, where their growing complexity obscures their decision-making process. Explainable AI fraud detection opens that box with two widely used techniques:
AI fraud model interpretability matters most for compliance, because regulators need to know why a transaction was blocked. In the US, when a model contributes to an adverse credit decision, lenders must provide specific reasons under the Equal Credit Opportunity Act, and the Fair Credit Reporting Act adds notice duties when consumer report data is involved. In the EU, GDPR restricts decisions based solely on automated processing that significantly affect individuals.
The EU AI Act adds nuance. It classifies AI used to assess creditworthiness as high-risk but explicitly excludes systems used to detect financial fraud. The European Commission’s draft guidelines interpret that exclusion narrowly, so a model built for fraud detection that also influences credit decisions may still fall into the high-risk category.
By embedding a layer of explainability into their models, organizations can create trustworthy, compliance-ready systems that balance algorithmic precision with regulatory accountability. Explainability is also a pillar of enterprise AI security and compliance as a parallel discipline to fraud prevention.
How Do AI Fraud Models Use Continuous Learning to Stay Ahead of Evolving Fraud?
AI fraud models stay ahead through continuous learning: they are monitored for drift, retrained on newly confirmed fraud, and in some cases updated in near real time. Federated learning lets institutions learn from shared fraud patterns without exchanging customer data, and adversarial testing hardens models against attackers who probe them.
AI in fraud detection gets better through constant improvement and feedback loops. Four practices keep adaptive AI fraud detection effective:
- Online learning vs batch retraining: Batch retraining rebuilds models on a schedule and suits stable patterns. Online learning updates models incrementally as new labels arrive, so the system reacts to fast-moving attacks. Many teams combine both and use champion-challenger testing to promote a new model only when it beats the current one.
- Reinforcement learning: It is a method where algorithms learn to make decisions by receiving feedback on their actions. This way, they can adjust to changing fraud patterns over time.
- Federated learning: Fraudsters reuse tactics across institutions, but privacy rules prevent banks from pooling customer data. Federated learning fraud prevention trains a shared model across organizations while each keeps its data in place; only model updates are exchanged.
- Adversarial defense: Machine learning algorithms are now being used against the institutions that pioneered them. Attackers probe models with small variations to find what slips through. Adversarial training, input validation, and limits on score feedback make models harder to game.
The next step is autonomous, multi-agent detection, where multiple specialized agents work across distributed networks to monitor different aspects of transactions simultaneously. In the future, we expect increased collaboration between human analysts and autonomous AI agents to create a far more formidable defense against evolving fraud tactics. Regular AI fraud model retraining remains the foundation that makes these advances reliable.
What Are the Challenges of AI Fraud Detection and How to Overcome Them?
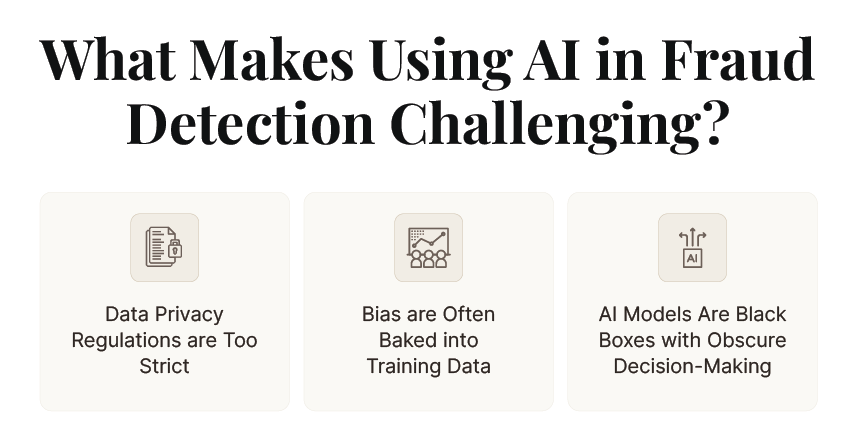
The three biggest challenges in AI fraud detection are false positives that block genuine customers, bias inherited from imbalanced training data, and compliance with privacy and AI regulations such as GDPR, FCRA, and the EU AI Act. Each can be managed with segment-level threshold tuning, fairness testing, and privacy-by-design governance.
1. False Positives and Customer Friction
False positives happen when genuine transactions get wrongly marked as fraud. This creates unnecessary problems, frustrates customers, and wastes resources.
Mitigation: Tune thresholds by customer segment and channel rather than globally, add device and behavioral context, and route medium-risk events to step-up authentication instead of a hard decline. Track AI fraud detection false positives as a business KPI alongside fraud losses.
2. Bias in Models
AI models learning from old data might amplify unfair patterns baked into this data. Demographic imbalance in training data can lead models to flag certain groups more often.
Mitigation: Test outcomes across customer segments before and after deployment, constrain proxy variables that encode protected attributes, and document decisions as part of an ethical AI strategy, where bias in fraud models is proactively managed.
3. Regulatory Compliance and Data Privacy
Fraud detection requires careful handling of strict data privacy regulations. GDPR, US state laws such as the California Privacy Rights Act (CPRA), FCRA, and the EU AI Act shape what data a model can use and how decisions are explained.
Mitigation: Build AI fraud compliance in from the start with data minimization, a clear legal basis for processing, audit trails for every decision, and human review for high-impact outcomes.
How Do You Implement Machine Learning in Fraud Detection?
To implement machine learning fraud detection, collect and prepare historical data, engineer features, select the right algorithms, train and validate the models, integrate them into real-time decision flows, and monitor and retrain them continuously. The six steps below form a repeatable framework for ML-based fraud detection.
Step 1: Data Collection and Preparation
Collect historical data encompassing both legitimate and fraudulent transactions to build a robust dataset. Always make sure that collected data is accurate, exhaustive, and properly preprocessed to train Machine Learning models and fuel the learning process.
Step 2: Feature Engineering
Extract relevant features from the datasets that empower Machine Learning models to effectively distinguish between legitimate and fraudulent activities. Examples include transaction velocity, time since last login, distance from usual location, and device age.
Step 3: Model Selection
Choose the right Machine Learning algorithms based on the nature of collected data and the specific fraud scenarios that enterprises need to detect. Pair supervised and unsupervised models where fraud labels are limited.
Step 4: Training and Validation
Train Machine Learning models using labeled data and validate the performance against industry-recognized metrics. Because fraud data is imbalanced, rely on precision, recall, and precision-recall curves rather than accuracy alone.
Step 5: Real-Time Integration
Enable real-time monitoring and response by seamlessly integrating the Machine Learning models into the existing fraud detection infrastructure.
Step 6: Continuous Monitoring and Improvement
Regularly monitor Machine Learning model performance and iteratively improve algorithms when new data is available. Add explainability and bias checks to every model release so fraud detection using machine learning stays accurate and auditable.
Build AI-Powered Systems to Counter Financial Threats
Why Is AI Fraud Detection No Longer Optional?
AI-powered detection systems have become vital safeguards against financial losses as organizations battle sophisticated financial threats. Traditional rule-based systems of yesteryear cannot match the adaptability and precision of artificial intelligence.
AI fraud detection is now the difference between proactive protection and reactive loss management. The organizations that lead will combine machine learning fraud detection with behavioral intelligence, explainability, and continuous learning, governed by clear compliance guardrails.
Damco brings AI and ML for financial services to life. Our AI application development for financial services, including custom fraud detection, helps you build fraud detection applications around your workflows, while our AI and ML development services for building enterprise fraud detection systems cover model engineering, explainability, and MLOps.
References:


