Key Takeaways:
- In regulated industries, a wrong training label can turn into wrong decisions about people.
- HITL data labeling reduces bias only when reviewers, guidelines, and checks are designed to find it.
- Treat model pre-labels as suggestions to verify, not answers to accept.
- Put subject-matter experts where a wrong label is costly, and send uncertain items to people first.
- Blind re-labels and seeded errors show whether reviewers are checking or rubber-stamping.
- Regulators rarely mandate labeling methods; they expect evidence of fit-for-purpose data.
If you lead AI, data, risk, or compliance at an insurer, bank, healthcare organization, or other regulated business, your models shape decisions about people. They learn from labeled training data, and much of that data is now pre-labeled by AI quickly and at scale, often just as confidently when the label is wrong. In regulated industries, a single labeling error, repeated across a dataset, can turn into a flawed decision that affects someone’s health, money, or livelihood. Human-in-the-loop (HITL) data labeling, also called HITL data annotation, reduces this risk by placing trained reviewers in the training loop to check what the model proposes. But human review only reduces bias when reviewers and guidelines are designed to find it.
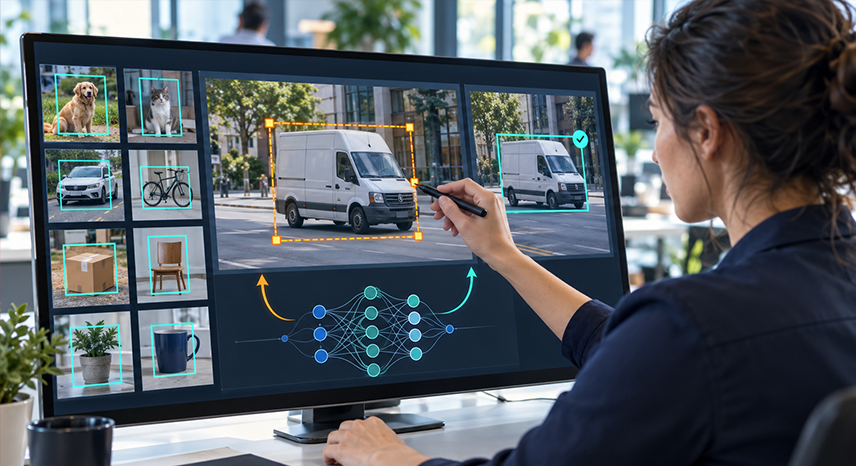
This blog separates the two meanings of human-in-the-loop AI, explains where bias enters training data, how human-in-the-loop AI workflows catch it, and what controls keep that review honest in healthcare, insurance, lending, fraud detection, hiring, and safety applications.
Why Is Automated Labeling Alone Not Enough in Regulated Industries?
Automated labeling has become the default starting point for building training data. The reason is simple. A model can label hundreds or thousands of data points per hour and handle volumes that would overwhelm human reviewers. It also applies the same labeling logic to every example. Labeling platforms such as Label Studio and Kili have made this workflow standard practice: a model proposes labels, and people review and correct them instead of labeling from scratch.
The weakness lies in where models fail. A model labels with the same confidence whether it is right or wrong. It can be wrong in the places that matter greatly in regulated work: rare conditions, ambiguous items, groups of people who were scarce in the training data, and context it was not trained on, such as a non-standard payslip. These errors do not average out as random noise. Because the model applies the same logic everywhere, a blind spot becomes a pattern repeated across the dataset.
A pattern of wrong labels costs some accuracy in most industries. But in sectors like insurance and healthcare, it can cost a lot more. A wrong training label can become a wrong decision about a person. It can mean a claim valued too low or a finding missed on a scan. The stakes are growing. Stanford’s[1] 2026 AI Index reports that documented AI incidents rose to 362 in 2025, up from 233 in 2024. That is the case for keeping people in the labeling loop.
That said, human review is not a cure on its own. In many cases, reviewers tend to accept the model’s suggestions without sufficient scrutiny. This lets the model’s bias pass straight through. Then, reviewers also bring assumptions of their own. Human review reduces bias only when reviewers, guidelines, and checks are designed to find it.
“In many industries where giant data sets simply don’t exist, I think the focus has to shift from big data to good data.”
– Andrew Ng, Founder of DeepLearning.AI and Landing AI
This guide builds on that premise. It separates the two meanings of human-in-the-loop and maps where bias enters training data. It also walks through the loop and the controls that make human review reliable.
What Are the Two Meanings of Human-in-the-Loop AI?
Before looking at where human review helps, it is worth being precise about which human review this guide means. Human-in-the-loop AI describes two different loops.
- Training-data oversight places people in the labeling loop. Here, they review, correct, and verify the data a model learns from.
- Decision-time oversight positions humans as the final decision-makers. They own the decisions the model informs and approve or override outputs before those outputs affect people.
The difference matters because these forms require different skills and accountability structures. A reviewer correcting mislabeled medical images during training needs clinical expertise and clear annotation guidelines. By contrast, a clinician approving a diagnosis recommendation at decision time needs diagnostic authority and the legal standing to take responsibility for the outcome.
This guide covers the first loop.
The role of people in the training-data loop is also shifting, from labeling everything to teaching where it counts. Both loops rest on the same principle: the model proposes, a person decides, and someone checks the person. In the training-data loop, the model proposes a label, and an annotator accepts or corrects it. Then a quality process checks whether the annotator caught what the model got wrong. The next section shows why the final check matters by tracing where bias enters training data.
Key Challenges in Data Labeling and How to Fix Them
Where Does Bias Enter Training Data, and Where Can Human Review Catch It?
Bias seldom enters training data at a single point. It can arrive with the sample, through the guidelines, through the annotators, through the model’s own pre-labels, and through corrections fed back after deployment. Human review meets each of these entry points. But it does not automatically fix them. The table below maps where annotation bias enters, what reviewers can catch, and how review itself can fail.
| Entry Point | How Bias Enters | What Human Review Can Catch | What Can Go Wrong |
|---|---|---|---|
Data Sampling Gaps |
Some groups, conditions, or document types are rare in the collected data. As a result, the model learns little about them. |
Reviewers can flag missing cases and under-represented groups as they work through the data. |
Reviewers flag gaps only if the guidelines ask them to look. Otherwise, the gap remains unnoticed. |
Labeling Guideline Limitations |
Vague, contradictory, or narrow instructions lead annotators to improvise. This becomes especially evident in subjective tasks like detecting harm or intent. |
Guideline audits and expert review catch definitions that build in assumptions. |
Poorly written guidelines propagate bias. Every annotator follows flawed instructions and multiplies errors. |
Annotator Background and Assumptions |
Background, training, and assumptions shape judgments, especially on subjective or culturally specific items. |
Diverse annotator pools and adjudication bring disagreement, and the reasons for it, into view. |
Majority voting can overrule a minority reading that was correct. |
Model-Generated Pre-Label Acceptance |
Reviewers tend to accept model suggestions without adequate scrutiny. Annotators learn from patterns shown in pre-labels and replicate them, even when non-representative. |
Blind re-labeling and seeded errors test whether reviewers judge independently. |
Pre-label acceptance allows model bias to pass into training data. Reviewers treat suggestions as answers. |
Post-Deployment Feedback Loops |
Corrections from production shape the next training set, so existing patterns can reinforce themselves. |
Reviewing corrections before they are reused can spot a pattern before it grows. |
Corrections fed back without bias checks repeat past decisions, including unfair ones. |
Two points follow from the table. First, human review is a control, and like any control, it can fail. The pre-label row shows the most common failure. A reviewer who accepts a pre-label without checking it has not reviewed anything. A pre-label is thus a suggestion, not an answer.
Second, much of this risk sits in data work that organizations undervalue. Data quality problems may compound into “data cascades,” downstream harms that are often invisible and delayed. HITL data labeling designed around the entry points above is one place to catch a cascade early.
Sampling gaps usually begin upstream, at collection, which Damco’s multimodal data collection guide covers. The use cases that follow show what reviewers catch when review is designed around these entry points.
What Are the Use Cases of HITL Data Labeling in Regulated Industries?
Six regulated industries show where HITL data labeling catches errors that automated systems miss on their own. These scenarios illustrate common patterns based on published research and industry practice.

1. Healthcare: Medical Imaging
- The risk without human review: A model pre-labels scans well for common presentations but misreads rare conditions and images from patient groups that were scarce in its training data, or images taken on unfamiliar equipment. Because the logic is the same for every image, the same miss repeats across the dataset.
- What trained reviewers catch: Clinicians and trained specialists recognize atypical presentations and image-quality problems that a general annotator would pass. They can also say which patient groups or conditions are missing from the set.
- The control that makes it reliable: Expert sign-off on the gold set. Disagreements between specialists are adjudicated by a senior clinician instead of settled by vote.
- The responsible AI link: A documented expert review shows that the training data was examined for the populations the model is meant to serve.
2. Insurance: Claims Photos and Documents
- The risk without human review: A model grades damage severity from photos and reads claim documents with confidence. But it misjudges unusual vehicles and properties, regional building styles, and documents whose meaning depends on context. One example is a repair estimate in a format it has not seen.
- What trained reviewers catch: Reviewers who understand claims spot severity misreads and misinterpreted documents. They also notice when errors cluster by region or claim type.
- The control that makes it reliable: Route low-confidence items to people first. Track error patterns by region. The coverage call itself stays with a person. Labeling improves what the model sees, not who decides.
- The responsible AI link: Insurers in states that have adopted the NAIC model bulletin are expected to govern the data behind their AI systems.
3. Lending: Income and Identity Documents
- The risk without human review: Extraction models trained on standard payslips and identity documents mishandle non-standard ones. These include gig-economy income statements, several sources of income, foreign documents, and names that do not match expected patterns. These errors fall hardest on applicants whose finances are less conventional.
- What trained reviewers catch: Reviewers catch extraction errors that would understate income or fail a valid identity check. They also flag document types of the model that have not been learned.
- The control that makes it reliable: Seeded-error audits place known mistakes in the review queue to confirm reviewers find them. Sampled re-labeling of non-standard documents adds a second check.
- The responsible AI link: A record showing that data used in credit-related models was checked for errors that could disadvantage particular applicants.
4. Financial Crime and Fraud Review
- The risk without human review: Labels on transactions and cases decide what a model learns to flag. Past investigations may have concentrated on certain regions, customer types, or names. The historical labels carry that concentration into the model.
- What trained reviewers catch: Reviewers check whether flagged patterns follow genuine risk indicators or stand-ins such as geography or nationality. They also question labels that rest on assumptions instead of evidence.
- The control that makes it reliable: A senior investigator adjudicates disputed labels. Regular review also tracks how labels are distributed across groups and regions.
- The responsible AI link: A record that labels were examined for over-flagging. This supports fair treatment of customers alongside financial crime obligations.
5. Hiring and HR Text
- The risk without human review: Models that classify applications, resumes, or employee text can learn proxy features. These include career gaps, school names, or wording patterns associated with gender, age, or background.
- What trained reviewers catch: Reviewers and guideline audits catch categories that reward or penalize proxies instead of job-relevant skills. They also flag non-traditional career paths the model misreads.
- The control that makes it reliable: Guideline audits of category definitions, plus a diverse annotator pool with adjudication. Decisions about candidates stay with people.
- The responsible AI link: The EU AI Act lists employment uses as high-risk. A documented review of labels supports the data governance evidence those systems need.
6. Transport and Safety Video
- The risk without human review: Labels for pedestrians, cyclists, vehicles, and hazards degrade at night, in rain, under occlusion, and during rare events, and interpolation between keyframes can drift without anyone noticing.
- What trained reviewers catch: Reviewers catch missed objects, identity switches, drifting boxes, and rare events the model under-labels.
- The control that makes it reliable: Full review of rare-event clips and of interpolated segments, which the video section below covers in more detail.
- The responsible AI link: Evidence that safety-relevant edge cases were labeled and checked, not assumed.
The common thread across all six settings is simple: in regulated settings, the people who label should understand what a wrong label costs. For a regulated organization, the next question is what regulators and frameworks expect of this work.
What Do Regulators and Frameworks Expect from Training Data?
In short, they expect evidence. Regulators and frameworks set expectations for the quality of training data and for how bias is examined. But they rarely prescribe how labels should be produced. The status described below is current as of October 2026.
I. EU AI Act
The EU AI Act Article 10[2] sets data and data governance requirements for high-risk AI systems. Training, validation, and testing data must be subject to governance and management practices that cover data preparation operations such as annotation and labeling. These practices must also include an examination for possible biases that could affect health and safety, harm fundamental rights, or lead to prohibited discrimination, together with measures to detect, prevent, and mitigate them.
The data must also be relevant, sufficiently representative, and, to the best extent possible, free of errors and complete for the intended purpose.
The timing has moved. The Digital Omnibus on AI, Regulation (EU) 2026/1744, in force since 27 July 2026, deferred these obligations. They now apply from 2 December 2027 for the high-risk uses listed in Annex III, such as recruitment and credit scoring, and from 2 August 2028 for AI in products covered by Annex I, such as medical devices.
Human oversight is a separate requirement under Article 14. It concerns the decision loop, not training data.
II. NIST AI RMF
The NIST AI Risk Management Framework is voluntary. It treats managing harmful bias as part of trustworthy AI across the lifecycle. It names three categories of bias: systemic, computational and statistical, and human-cognitive. The third category is a reminder that annotators and reviewers can be a source of bias as well as a check on it. NIST says the framework is being revised under the July 2025 White House AI Action Plan, so organizations should check the current version before relying on its wording.
III. Sector Rules
In US insurance, the NAIC Model Bulletin on the Use of Artificial Intelligence Systems by Insurers[3] was adopted by the NAIC in December 2023. It expects insurers to maintain a written AI systems program with governance and risk management controls, including controls over the quality of data and the analysis of bias.
None of these texts mandates a particular labeling method, and none requires HITL by name. Regulations rarely prescribe a labeling method. They expect you to show your training data is fit for purpose. A documented HITL process, with named reviewer roles, written guidelines, agreement measures, and audit records, is one practical way to produce that evidence.
What a documented process can show depends on where people sit in the loop, which the next section sets out.
Where Do Humans Sit in the HITL Data Annotation Loop?
A HITL data annotation workflow has six points where a person adds value. Each one needs the right kind of person: a subject-matter expert where the judgment is specialized or a wrong label is costly, and a trained general reviewer where the task is well defined.

- Writing guidelines and building the gold set. Guidelines define each category, its edge cases, and worked examples. The gold set is the expert-validated reference that annotators and model outputs are measured against. Subject-matter experts should lead this step, with input from the people who will apply the guidelines.
- Reviewing model pre-labels. Annotators accept, correct, or reject what the model proposes. Dataloop’s documentation, for example, describes model pre-annotations moving straight into human labeling and QA review tasks. Trained reviewers handle most items, and experts handle the specialized ones.
- Routing uncertain items to people first. Active learning sends the items the model is least sure about to human review ahead of the rest. Kili describes this as directing expert attention to the cases where the model’s predictions are least confident. In regulated work, subject-matter experts should take the flagged items.
- Adjudicating disagreements. When annotators disagree, a senior reviewer or subject-matter expert decides and records why, and recurring disagreements feed back into the guidelines.
- Auditing quality. Sampled audits check labels against the gold set and measure agreement between annotators. The sample should include labels the model was confident about, because routing by uncertainty cannot catch an error the model is sure of. A QA team that is independent of the annotators being audited should own this step.
- Checking drift after deployment. Production data and corrections are reviewed for new patterns before they enter the next training set. Trained reviewers screen the data, and experts review flagged cases.
Labeling platforms implement these steps in different ways. What matters is that each step exists, has an owner, and leaves a record. The guiding rule for placement is to put people where the model is least sure, not where it is fastest to check. Placing people well is half the work, though. The other half is confirming that they are doing the job.
What Controls Keep Human Review Honest?
The loop decides where people sit. Controls test whether they are working. The controls fall into two groups. The first group works against rubber-stamping, where reviewers approve whatever the model proposes. The second group works against annotator bias, where reviewers add assumptions of their own. Together, they form a checklist that an organization can adopt as it stands.
1. Controls Against Rubber-Stamping
- Blind re-labeling: Have a different reviewer label a sample of items without seeing the pre-label, then compare the results with the reviewed labels. Wide gaps show where review is following the model rather than checking it.
- Seeded errors: Place known mistakes in the review queue and measure whether reviewers catch them. The catch rate is the most direct evidence that review is working.
- Uncertainty cues: Show reviewers where the model is likely to be wrong. In a controlled study of 120 participants reviewing AI-generated object detection annotations, Kassem Sbeyti et al.[4] found that participants shown visual cues of localization uncertainty for bounding boxes produced higher-quality labels and worked faster, and that the cues shifted their attention toward high-uncertainty predictions.
- Change-rate tracking: Monitor how often each reviewer modifies pre-labels, and investigate rates that fall over time. If reviewers never change a pre-label, you are not reviewing; you are approving.
2. Controls Against Annotator Bias
- Diverse annotator pools: Include reviewers whose backgrounds reflect the people the model will affect, especially for subjective or culturally specific items.
- Agreement between people: Measure inter-annotator agreement between reviewers, not only agreement with the model. High agreement with the model can hide a shared blind spot.
- Adjudication: Have a senior reviewer or subject-matter expert resolve disputed labels and record the reason, so the decision can be audited later.
- Guideline audits: Review category definitions periodically for any that fit some groups, regions, or formats poorly.
- Fair pay and realistic targets: Set pay and throughput targets that reward careful work. Rewarding reviewers for catching seeded errors keeps careful review worthwhile.
If you are assessing your own labeling process, this checklist is a practical place to start.
These controls apply to every data type, but one type tests them harder than the rest.
Data Annotation vs. Labeling for Enterprise-Grade AI Systems
Why Is HITL Video Annotation the Hardest Case?
Video multiplies every labeling problem by time. Even a short video clip contains thousands of frames. Each label has to stay correct across all of them as objects move, change appearance, and disappear behind other objects. A label that is right in one frame and wrong in the next teaches the model an inconsistent picture of the world.
Four features make video the hardest case for review.
- Labels must stay consistent across frames.
- Objects must keep the same identity when they leave the view and re-enter it, as when a pedestrian steps behind a parked vehicle.
- Interpolation between keyframes, which fills in the frames not labeled by hand, can drift and assign the wrong box or class to intermediate frames.
- Rare events, the moments that matter most for safety, are brief and easy to miss in hours of routine footage.
These are the points where reviewers add the most value. They check interpolated segments instead of only keyframes, confirm identity across occlusion, and review rare-event clips in full instead of sampling them.
This section covers the human review layer only. For video annotation types and techniques, such as tracking, keyframe strategy, and segmentation, see Damco’s computer vision data labeling guide. In video, a label has to stay right across every frame, not just one.
How Does Damco Run HITL Data Labeling?
Damco runs HITL data labeling as a quality control, built on the structures this guide describes, including:
- Reviewers matched to risk: Annotation specialists with domain knowledge label the data. Subject-matter experts validate annotations where a wrong label is costly, as with medical images, insurance claims, and financial documents.
- The loop, designed with the client: Guidelines and a gold set come first. Pre-label review, routing of uncertain items, adjudication, and quality audits follow.
- The controls, measured and reported: Blind re-labels, seeded errors, and agreement measures show clients whether review is working, not only whether it took place.
- Documentation: Guidelines and their versions, reviewer roles, adjudication decisions, and audit results are recorded in a form that can support a client’s responsible AI evidence.
Our data annotation services cover image, video, text, and audio data for healthcare, finance, insurance, automotive, and other sectors. Across all of them, we measure human review as a quality control, not just a step in the pipeline.
If you are planning a model for a specific regulated use case, we would welcome a conversation about how HITL labeling could be designed for it, including where experts are needed and what evidence your governance team is likely to expect.
Final Thoughts
Human review is not a cure on its own. It works only when reviewers, guidelines, and controls are built to catch bias. Regulators rarely name HITL, but they expect evidence that training data is fit for purpose, and a documented HITL process can help produce that evidence. If you are building AI for a regulated use case, Damco can help you design a labeling process that stands up to that scrutiny. Talk to our annotation team to see where your current workflow stands.
References:
- 1. Stanford
- 2. EU Artificial Intelligence Act
- 3. NAIC
- 4. arXiv
Frequently Asked Questions
HITL data labeling is a way of building AI training data in which people review, correct, and verify labels, usually labels that a model has proposed first. Instead of labeling every item by hand or trusting the model's labels as they are, trained reviewers check the model's suggestions, take the items the model is least sure about, and resolve disagreements.
Human-in-the-loop labeling reduces bias only when reviewers, guidelines, and checks are designed to find it. Without that design, reviewers tend to accept the model's suggestions, which passes the model's bias into the training data, and they can add assumptions of their own.
No regulation currently mandates HITL data labeling as a method, but several expect organizations to show that their training data is fit for purpose. Article 10 of the EU AI Act requires data governance for high-risk systems, including an examination for possible biases. The NIST AI RMF is voluntary, and the NAIC model bulletin addresses insurers' AI governance. A documented HITL process is one way to produce the evidence these regulations expect.
Human-in-the-loop AI often refers to people in the training-data loop, while human oversight usually refers to people in the decision loop. In the training-data loop, people label, review, and correct the data a model learns from. In the decision loop, people own the decisions a deployed model informs and can approve or override its outputs.
You need subject-matter experts to label data when a wrong label is costly, or the judgment calls for specialized knowledge. Typical examples include medical images, insurance claims, credit documents, and financial crime cases. Experts are most valuable when they write guidelines, build and sign off the gold set, adjudicate disagreements, and review items the model is least sure about.


